Prompt evidence, preserved
The workspace keeps the original question, returned brands, cited domains, date, and model together.
EXAMPLE BUYER PROMPT“Which SEO platforms suit a five-person agency that needs client reporting and AI visibility tracking?”
- Google search84
- AI answers68
- Authority73
- Social61
Example VisibleGen workspace using demonstration data. It does not represent a customer account or a published study result.
The short answer
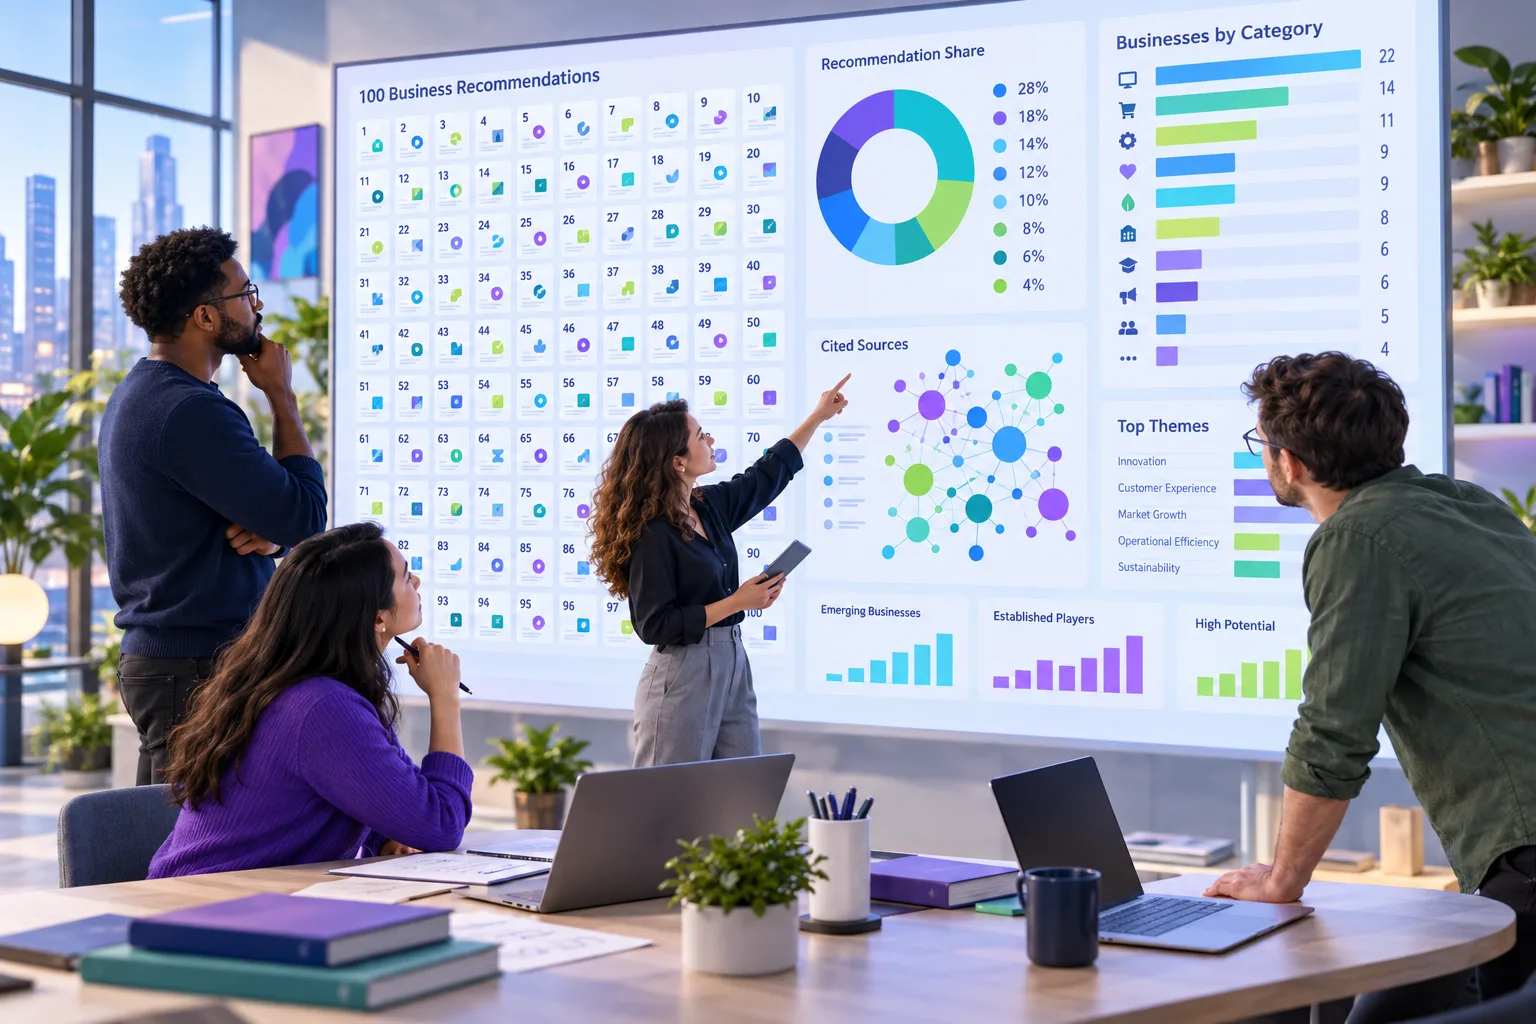
We are testing which businesses ChatGPT recommends across 100 controlled buying prompts and which sources it uses to support those answers. Until every response is preserved and coded, we will not publish a winner list or precise-looking percentages.
The research question is simple: when a buyer adds a location, audience, budget, or specialist requirement, what changes in the shortlist—and what public material appears beside that recommendation?
How the 100-prompt test was designed
We created ten buying situations and wrote ten natural-language variations for each one. Prompts ranged from broad discovery—“What are the best options?”—to decision-stage requests such as “Which provider is best for a small team that needs monthly client reporting?”
- Separate branded from non-branded prompts. A brand query measures recognition; a category query measures discovery.
- Keep the buyer constraint visible. Location, company size, budget, and desired outcome can change the recommendation.
- Record the full answer. We capture recommended brands, order, wording, linked sources, unlinked mentions, and stated reasons.
- Code uncertainty. “Consider,” “a strong option,” and “the best choice” do not mean the same thing.
- Repeat over time. A single answer is an observation, not a trend.
What the final dataset will show
The published table will list each prompt, the brands returned, their order, the reason given, the cited domains, and the date of collection. It will also separate a brand mention from a direct recommendation and a linked citation.
We will report category and specialist patterns only when the coded answers support them. Readers will be able to inspect the raw rows rather than relying on a headline alone.
Can an answer engine explain exactly what the business does and who it serves?
Do credible sites, customers, and industry sources describe the business consistently?
Does the site answer comparison, suitability, location, pricing, and outcome questions directly?
The hypotheses we are testing
1. They owned a recognizable category
“All-in-one solutions for modern growth” is difficult to classify. “Local SEO software for multi-location restaurants” gives the model a useful entity, audience, and job to connect.
2. Other sources may support the same story
We will check whether reviews, news coverage, association pages, comparison articles, community discussions, and trusted directories appear beside recommendations more often than company-owned pages alone.
3. Their proof matched the buyer’s question
A prompt asking for an agency tool rewards agency evidence: white-label reporting, account scale, workflow controls, and client outcomes. Generic traffic claims do not answer that request.
4. Their information was consistent
Conflicting names, locations, service descriptions, and pricing language create uncertainty. Consistency across the site and third-party profiles makes a business safer to describe.
What to measure in your own study
Start with five metrics: recommendation presence, citation presence, recommendation position, reason given, and source type. Then add competitor overlap and change over time. Keep the original answers beside every score so a stakeholder can see the evidence.
The most important question is not “Did the model say our name?” It is “What evidence made the model comfortable recommending us—and what evidence is missing?”
A practical next step
Write twenty prompts that real buyers might ask before choosing your category. Run the same set across the assistants important to your audience. Record mentions and sources, then group the gaps into site clarity, third-party authority, local evidence, and missing content. VisibleGen’s AI Visibility Tracking and AI Source Opportunities are designed for that workflow.